
The other I threw away, and the only thing that told them apart was a control group that most people building trading systems never bother to build.
Here’s what the control saw that my eyes couldn’t.
What a control group is, and why trading skips it
In a drug trial you don’t just give people the drug and check if they improve. You give a matched group a sugar pill, because people improve for all sorts of reasons unrelated to the drug. The placebo group tells you how much “improvement” comes from noise alone. The drug has to beat that, not zero.
Trading backtests almost never do this. You test your idea, you get a positive number, you trade it. You never ask the equivalent of “how well would a deliberately meaningless version of this have done on the same data?” Without that baseline you can’t tell a real edge from the market handing out lucky results to anyone who runs enough tests.
So I built the sugar pills, eighty of them.
Building 80 meaningless strategies
My real ideas key off specific price levels. To build controls, I kept the entire machine identical — same instrument, same period, same trade management, and corrupted only the one thing that was supposed to carry the edge: I moved the trigger levels to arbitrary, meaningless offsets. Eight offsets across ten price regions: eighty complete strategies, each structurally identical to a real one, each pointed at levels that should hold no information.
A real edge should stand clear of this crowd. A fake one should sit right in the middle of it. Then I ran both of my candidate strategies against the pack.
Candidate one: the intuitive idea: “levels react”
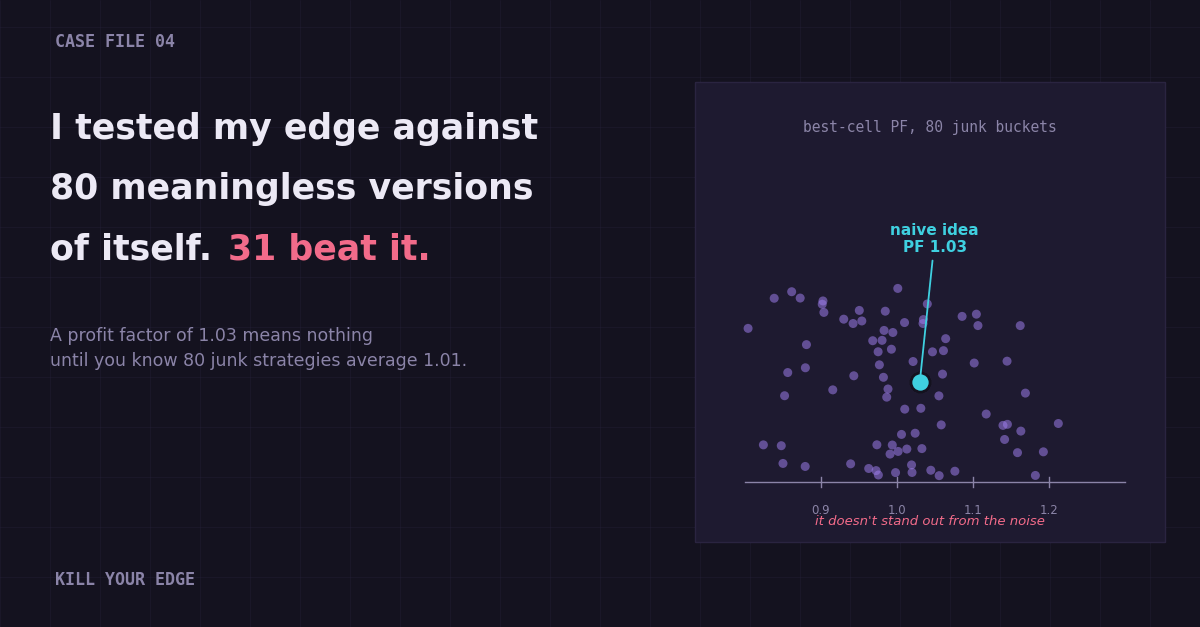
The first idea was the obvious one: price approaches a level, price reacts, you trade the reaction. It backtested positive: profit factor 1.03 in-sample.
I almost stopped there. A positive number feels like an edge. But 1.03 is barely above breakeven, so before trading it I ran it against the eighty controls. The result:
naive “levels react”: IS PF 1.03, OOS PF 0.98, positive in 4 of 7 years
80 meaningless buckets: 31 of them scored a BETTER best-cell than 1.03
Thirty-one of the eighty meaningless strategies beat it. It fell out-of-sample below breakeven, and it only worked in four years out of seven. This wasn’t a weak edge — it was no edge. A number that sat in the middle of the noise. I threw it away, and the control is the only reason I knew to.
Candidate two: the specific idea — cross, geometry, regime
The second idea looked superficially similar but was mechanically different: not “a level reacts” but a specific cross of the level with tuned geometry and a regime filter. It backtested at profit factor 1.34, win rate 58.4%, over 514 trades. Same eighty controls:
cross + geometry + regime: 58.4% completion, PF 1.34, +3.29 SD above the controls
80 meaningless buckets: 0 of them beat it
positive in 6 of 7 years, IS 1.29 / OOS 1.38 (held out-of-sample)
None of the eighty junk versions came close. It sat more than three standard deviations clear of the noise, held up out-of-sample, and worked in six years out of seven. That is what a real effect looks like against a control. It’s in my live book today.
The two numbers side by side
This is the whole point of the post:
PF vs 80 controls verdict
naive “levels react” 1.03 31/80 beat it noise → discarded
cross + geometry 1.34 0/80 beat it edge → traded
Two ideas that a human would describe the same way, “I trade off price levels”, and the control group cleanly separated them. Without it, I’d have looked at both positive backtests and had no principled way to tell which was real. I might well have traded the 1.03, because “it’s positive” is exactly the trap. The control is what turned “both look fine” into “one is signal, one is noise.”
The honest coda: even the real edge is fragile
One more number, because leaving it out would be the kind of thing this whole series is against. The winning strategy’s 1.34 profit factor assumes optimistic fills. Add realistic slippage:
0 slippage (optimistic): 58.4% WR, PF 1.34, +$7.03 / trade
2 ticks (realistic): 53.1% WR, PF 1.07, +$1.78 / trade
Even the strategy that passed every control erodes toward marginal once real-world friction is priced in. Passing the control means the edge is real. It does not mean the edge is large, or that it survives contact with the market untouched. Real, small, and fragile is a very different thing from fake, but it’s still a long way from easy money.
The reproducible test
Run it on any strategy you have:
Keep your whole system fixed. Corrupt only the component that’s supposed to hold the edge, randomize the levels, shuffle the signal, offset the trigger. Build several dozen.
Run your exact evaluation, including any parameter optimization, on your real strategy and on every corrupted one.
Compare. Where does your real result fall in the distribution of meaningless ones? Several standard deviations clear is evidence. Sitting in the pack, like my 1.03, beaten by 31 of 80 junk buckets, is not an edge, however positive the raw number looks.
The lesson generalizes far past trading: a positive result is only as meaningful as the control you tested it against. Two of my strategies were positive. One was real and one was noise, and they looked identical until I gave each of them eighty meaningless twins to be compared against. The numbers didn’t change. What changed was that they finally had something to be measured against.
I write these up as I hit them — mostly places my own testing fooled me. If they’re useful, my email’s janheger89@gmail.com.